 OnCricketBetting
Cricket Match Prediction Models & Data Analysis
 Available in US
Predicting cricket matches is an exercise in structured uncertainty. No method — statistical, intuitive, or algorithmic — can consistently predict outcomes with certainty, because cricket is a sport where a single delivery can change the trajectory of an entire match. A run-out, a dropped catch, a sudden rain interruption, a bowler finding an unexpected crack on the pitch — these are not edge cases; they are the fabric of the sport. Yet prediction is exactly what betting demands. Every time you place a wager, you are implicitly stating a probability, and the quality of that probability estimate determines your long-term profitability.
The good news is that while perfect prediction is impossible, structured prediction is very much possible. Bettors and analysts use a range of methods — from pure statistical modelling to subjective expert assessment to machine-learning algorithms — and each method has strengths, weaknesses, and blind spots. The smartest approach is not to pick one method and ignore the rest but to understand what each method does well, where it fails, and how to combine multiple approaches into a prediction framework that is more robust than any single method alone.
This guide surveys the major prediction methods used in cricket betting, explains how each one works in practice, and explores where the field is heading as data availability and computing power continue to expand.
Using Statistical Models to Predict Match Outcomes
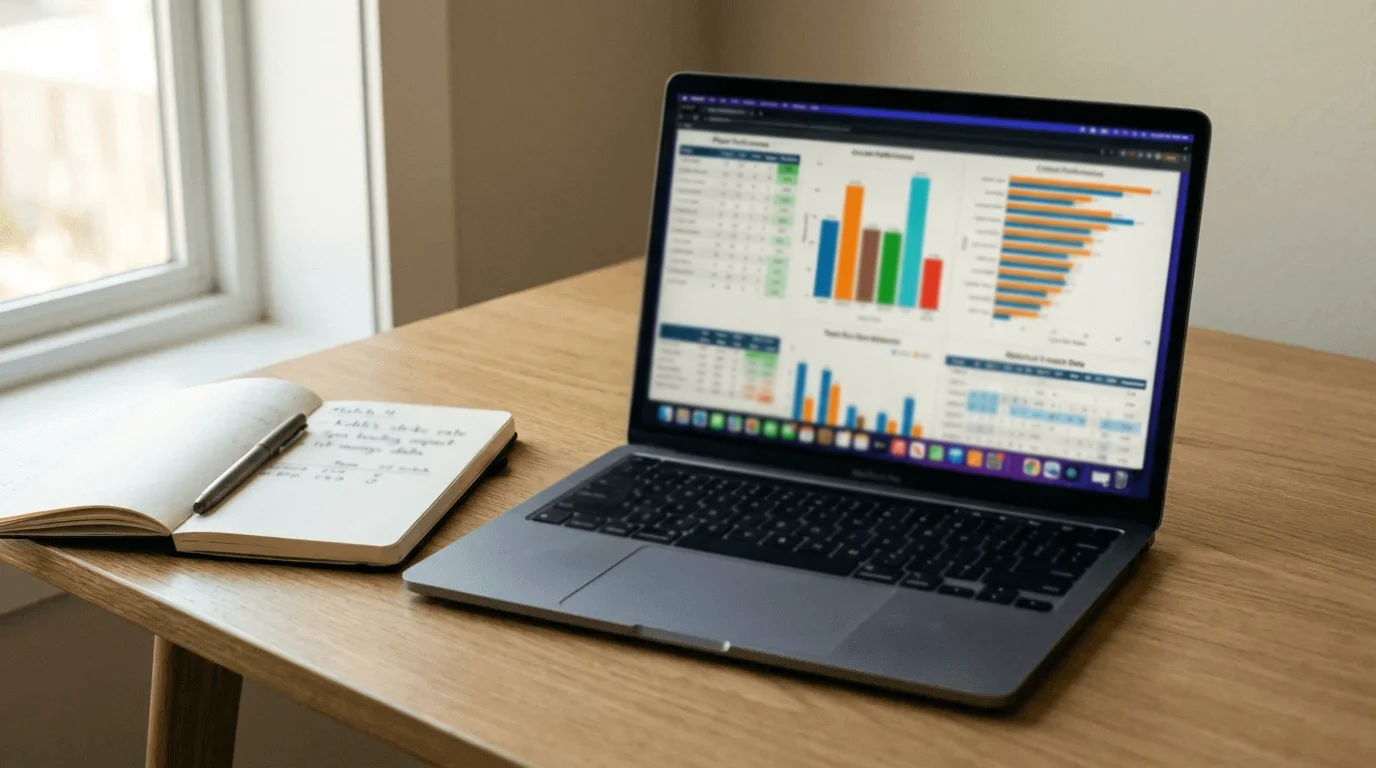
Statistical modelling is the backbone of serious cricket prediction. At its simplest, a statistical model takes historical data — team records, player averages, venue statistics, conditions data — feeds it through a mathematical framework, and produces a probability estimate for each possible outcome. The appeal is objectivity: a model does not care about media narratives, does not get excited about a player's reputation, and does not overweight the most recent result.
The most common starting point for cricket modelling is a team strength rating system. These systems assign each team a numerical rating based on their results history, with adjustments for the quality of opposition faced, the format, and home or away advantage. The ratings are then used to calculate win probabilities for upcoming matches. The Elo rating system, originally developed for chess, has been adapted for cricket by several independent analysts and provides a surprisingly effective baseline for match prediction. More sophisticated models incorporate format-specific ratings, venue adjustments, and rolling form windows that give more weight to recent performances.
Player-level models add granularity by assessing individual contributions rather than treating teams as monolithic units. A batting model might estimate each batter's expected runs based on their historical performance in the relevant format, at the specific venue, against the type of bowling attack they will face. A bowling model does the equivalent for each bowler. These individual predictions are then aggregated to produce a team-level expected score. Player-level models are more data-intensive and more complex, but they capture information that team-level models miss — such as the impact of a single key player being unavailable or a debutant being included.
The limitation of statistical models is that they are backward-looking by construction. They can only process data that has already been generated, which means they struggle with novel situations — a player returning from a long injury layoff, a newly laid pitch with no performance history, or a tactical innovation that changes how a team plays. Models are excellent at identifying base rates and structural patterns, but they need to be supplemented with forward-looking information that numbers alone cannot capture.
Form Analysis: Reading the Recent Signal
Form analysis focuses on recent performances to assess a team's or player's current trajectory. Where statistical models emphasise long-term base rates, form analysis asks a different question: what has happened in the last five to ten matches, and does it suggest the team or player is performing above or below their expected level?
The value of form analysis lies in capturing short-term factors that long-term models cannot. A batter who has made three consecutive fifties may be in a groove — seeing the ball well, moving their feet decisively, timing their shots cleanly. A bowler who has taken wickets in every match of a series may have found a rhythm with their action or identified a specific length that is causing problems. These short-term performance signals are real, and ignoring them means missing information that can improve your predictions.
The danger of form analysis is overweighting it. Statistical research across multiple sports consistently shows that short-term streaks are less predictive than people intuitively believe. A batter's last three innings explain a small fraction of the variance in their next innings — far less than their career average, the venue, and the bowling attack they will face. The human brain is wired to see patterns in sequences, and this pattern recognition instinct causes bettors to overreact to hot streaks and cold spells that are often nothing more than normal statistical variance.
The practical approach is to use form as a modifier rather than a foundation. Start with the structural prediction from your statistical model or base-rate analysis, and then adjust modestly based on recent form. If a player's career T20 average is 28 and they have scored 50, 65, and 40 in their last three innings, your prediction should shift upward — but not to 50. Something in the range of 32-35 represents a reasonable form-adjusted estimate that gives appropriate weight to both the long-term base rate and the recent signal.
Expert Opinion: The Human Edge
Expert analysis — whether from former players, specialist commentators, or dedicated cricket analysts — brings something to prediction that no model can replicate: contextual judgment. An experienced cricket mind can watch a team warm up, observe a batter's body language at the crease, read a captain's field placement choices, and draw conclusions about the likely trajectory of a match that no dataset can capture.
The strength of expert opinion lies in its ability to process qualitative information. A former fast bowler can look at a pitch and tell you whether the cracks will open up on day three or hold together. A batting coach can watch two overs of net practice and assess whether a player is timing the ball well or struggling with their technique. This qualitative judgment is particularly valuable in situations where statistical data is thin — debutants with no international record, newly laid pitches with no performance history, or tactical matchups that have never occurred before.
The weakness of expert opinion is its vulnerability to cognitive biases. Experts are human, and humans are susceptible to recency bias, confirmation bias, authority bias, and narrative-driven thinking. A former player might overvalue the impact of a specific bowler because they personally found that bowler difficult to face. A commentator might underestimate a team because the media narrative surrounding them is negative. Expert opinion is most useful when it is specific and observational — "the pitch has more moisture than expected, which will help the seamers in the first session" — and least useful when it is vague and narrative-driven — "this team just has a winning mentality."
For betting purposes, the optimal use of expert opinion is as a supplement to statistical analysis, not a replacement for it. When an expert's assessment aligns with your model's prediction, it increases your confidence. When it contradicts your model, it is worth investigating why — the expert may be seeing something your model cannot capture, or they may be falling prey to a bias that your model correctly ignores.
AI and Algorithmic Prediction: The New Frontier
Machine learning and artificial intelligence have entered cricket prediction with increasing sophistication over the past several years. Companies like CricViz have developed proprietary models that process ball-by-ball data to generate expected scores, win probabilities, and player valuations that go beyond traditional statistics. These algorithmic approaches can identify patterns in massive datasets that human analysts might miss, and they can update predictions in real time as a match unfolds.
The most common machine-learning approaches in cricket prediction include gradient boosting models trained on historical match data, neural networks that process ball-by-ball sequences, and Bayesian models that update probabilities dynamically as new information arrives during a match. These models excel at in-play prediction, where the volume of data being generated in real time — runs, wickets, dot balls, boundary frequency, bowling speed, shot selection — is too large for human analysis to process efficiently.
However, AI models share a fundamental limitation with simpler statistical models: they are only as good as the data they are trained on. If the training data does not include a relevant scenario — a match played at a brand-new venue, a format innovation like the Impact Player rule in the IPL, or a team that has dramatically changed its playing style since the last data collection — the model's predictions for that scenario may be unreliable. Additionally, AI models can struggle with small sample sizes, which are common in cricket when analysing specific player-versus-player matchups or venue-specific performance in less frequently used grounds.
The practical implications for bettors are twofold. First, if you have access to algorithmic predictions — whether through subscription services, publicly shared models, or your own modelling efforts — they are a valuable input that should be weighted alongside your statistical analysis and expert assessment. Second, the market is increasingly efficient because algorithmic models are being used by both bookmakers and sophisticated bettors. The edges that existed ten years ago, when bookmaker models were simpler and fewer bettors used data-driven approaches, have narrowed. Finding value in 2026 requires either a superior model, superior qualitative information, or the ability to combine both into a prediction framework that is more complete than what the market is using.
The Prediction You Cannot Make
Every prediction method shares one honest limitation: they all assume that the future will resemble the past in some structured way. Statistical models assume past patterns will repeat. Form analysis assumes recent trends will continue. Expert opinion assumes that experience is a reliable guide. AI models assume that training data captures the relevant dynamics. Most of the time, these assumptions hold well enough to produce useful predictions. But cricket, more than almost any other sport, has a talent for producing moments that no method anticipated — the unheralded bowler who delivers a spell for the ages, the pitch that behaves nothing like its history suggested, the team that collectively exceeds every individual prediction by a margin that defies explanation. The best prediction framework is one that accommodates this irreducible uncertainty rather than pretending it does not exist. Build your model. Consult the experts. Run the algorithm. Then leave a margin for the possibility that cricket will do what it has always done: surprise everyone, including you.
